The cheapest LLM API is Llama 3.1 8B on DeepInfra, at $0.02 per million input tokens and $0.04 per million output tokens. It's an old, small model, though. The cheapest models worth building on are GPT-6 Luna and Claude Haiku 5.5, both $0.10 in and $0.50 out, and Google's Gemini API has the best free tier.
The token price isn't the whole bill, either. Some cheap models think so much that one finished task costs more than it does on a model with 10 times the token price. I build AI chatbots and agents for a living, and the API bill is the number I watch most. Below are the cheapest LLM APIs per token and per finished task, the cheapest providers for open models, and the free options. To price your own app, use my LLM cost calculator.
What is the cheapest LLM API?
The cheapest LLM API is Llama 3.1 8B on DeepInfra at $0.02 per million input tokens and $0.04 output, and the cheapest current model is Alibaba's Qwen3.7-Flash at $0.03 and $0.13. Here's the cheapest pick for each kind of buyer:
| Pick | Model | Price per 1M tokens (in / out) | Why |
|---|---|---|---|
| Cheapest overall | Llama 3.1 8B on DeepInfra | $0.02 / $0.04 | Old and small, but fine for sorting and tagging text |
| Cheapest current model | Qwen3.7-Flash (Alibaba Cloud) | $0.03 / $0.13 | For prompts up to 32K tokens; longer prompts cost more |
| Cheapest newer open model | gpt-oss-20b on DeepInfra | $0.03 / $0.14 | OpenAI's open model, which also runs on a 16GB computer |
| Cheapest from a big US lab | GPT-6 Luna or Claude Haiku 5.5 | $0.10 / $0.50 | Haiku scores higher on Artificial Analysis (36 vs 28) |
| Most quality per dollar | GPT-6.1 Terra | $1.00 / $5.00 | Scored 38 at medium effort for $0.17 a test task |
| Cheapest from DeepSeek | DeepSeek V4.1 Flash | $0.30 / $1.20, half price off-peak | 1M-token context, and cached input at $0.006 |
| Best free option | Gemini 3.8 Flash on Google's free tier | $0 | Rate-limited, and Google uses your prompts to improve its products |
Prices are list prices in US dollars per million tokens, from each provider's own pricing page. A million tokens is roughly 750,000 words.
What is the cheapest LLM API with good quality?
GPT-6.1 Terra gives the most quality for the money: on Artificial Analysis's tests, it scored 38 at medium effort for $0.17 a task, barely more than the cheapest models and far smarter, even though its tokens cost 10 times more than Claude Haiku 5.5's. Per token, GPT-6 Luna and Claude Haiku 5.5 are the cheapest good models.
Per-token prices only tell half the story. Reasoning models write thousands of hidden "thinking" tokens before they answer, and you pay for every one as output. A cheap model that thinks for ages can cost more per job than a pricier one that gets to the point. Here's what each model cost to run one test task on Artificial Analysis's leaderboard, cheapest first:
| Model (thinking setting) | Price per 1M tokens (in / out) | Intelligence Index | Cost per test task |
|---|---|---|---|
| GPT-6 Luna (high) | $0.10 / $0.50 | 21 | $0.07 |
| MiMo-V2.6-Flash | $0.14 / $0.28 | 27 | $0.13 |
| GPT-6 Luna (max) | $0.10 / $0.50 | 28 | $0.15 |
| Claude Haiku 5.5 (high) | $0.10 / $0.50 | 30 | $0.16 |
| GPT-6.1 Terra (medium) | $1.00 / $5.00 | 38 | $0.17 |
| GPT-6.1 Terra (high) | $1.00 / $5.00 | 42 | $0.26 |
| Claude Haiku 5.5 (max) | $0.10 / $0.50 | 36 | $0.41 |
| MiniMax-M3.1-Flash | $0.15 / $0.60 | 29 | $0.49 |
| GLM-5.3-Flash | $0.15 / $0.50 | 28 | $0.58 |
| GPT-6.1 Sol (high) | $2.00 / $10.00 | 50 | $0.59 |
| DeepSeek V4.1 Flash (max) | $0.30 / $1.20 | 33 | $0.60 |
| Gemini 3.5 Flash-Lite | $0.30 / $2.50 | 12 | $0.69 |
| Gemini 3.8 Flash (high) | $0.75 / $3.75 | 31 | $7.77 |
| Claude Opus 5.5 (max) | $4.00 / $20.00 | 59 | $10.04 |
The standout is Gemini 3.8 Flash. Its token price looks mid-range, but it thinks so much that one test task costs $7.77, about 45 times more than GPT-6.1 Terra at medium effort, for a lower score.
For short jobs, like a chatbot reply with thinking set low or turned off, the per-token price is what you pay. For long, multi-step jobs like coding agents, cost per task is the number to watch.
LLM API pricing comparison: the 15 cheapest models
This LLM API pricing comparison lists the 15 cheapest of the 38 models I track, sorted by a typical mix of three input tokens to every output token. All prices are US dollars per million tokens.
| Model | Provider | Input | Cached input | Output | Context | Quality score |
|---|---|---|---|---|---|---|
| Llama 3.1 8BOld and small | DeepInfraOpen model | $0.02 | – | $0.04 | 128K | – |
| Qwen3.7-FlashPrompts up to 32K tokens | Alibaba Cloud | $0.03 | $0.003 | $0.13 | 1M | – |
| gpt-oss-20b | DeepInfraOpen model | $0.03 | – | $0.14 | 128K | – |
| Amazon Nova Micro | Amazon Bedrock | $0.035 | $0.00875 | $0.14 | 128K | – |
| Command R7B | Cohere | $0.0375 | – | $0.15 | 128K | – |
| gpt-oss-120b | DeepInfraOpen model | $0.037 | – | $0.17 | 128K | – |
| Ministral 3 3B | Mistral | $0.10 | $0.01 | $0.10 | 256K | – |
| Gemma 4 26B A4B | DeepInfraOpen model | $0.07 | – | $0.34 | 256K | – |
| Ministral 3 8B | Mistral | $0.15 | $0.015 | $0.15 | 256K | – |
| Llama 3.3 70B | DeepInfraOpen model | $0.10 | – | $0.32 | 128K | – |
| MiMo-V2.6-Flash | XiaomiOpen model | $0.14 | $0.0028 | $0.28 | 1M | 27 |
| Claude Haiku 5.55x the price on prompts over 100K tokens | Anthropic | $0.10 | $0.01 | $0.50 | 1M | 36 |
| GPT-6 Luna | OpenAI | $0.10 | $0.01 | $0.50 | 1M | 28 |
| Qwen3.8-Flash | Alibaba Cloud | $0.15 | $0.015 | $0.47 | 1M | – |
| GLM-5.3-Flash | Z.aiOpen model | $0.15 | $0.03 | $0.50 | 1M | 28 |
The quality score is the Artificial Analysis Intelligence Index, which runs every model through the same tough reasoning, coding, and agent tests, at each model's best setting. Higher is smarter, and a dash means it hasn't been scored.
The other 23 models, including every flagship, are in the full LLM API price list on my LLM cost calculator, which also works out what each one would cost your app per request and per month.
Who are the cheapest LLM API providers?
DeepInfra is the cheapest LLM API provider for open models: it sells gpt-oss-120b for $0.037 per million input tokens and $0.17 output, about a quarter of what Groq, Together AI, and Fireworks AI charge. Anyone can host an open model, so the provider you pick can change the price more than the model does. Here's what seven providers charge for the same two models, per million tokens:
| Provider | gpt-oss-120b (in / out) | DeepSeek V4.1 Flash (in / out) | Worth knowing |
|---|---|---|---|
| DeepInfra | $0.037 / $0.17 | $0.14 / $0.42 | The cheapest for both. Its DeepSeek price is 30% off the usual $0.20 / $0.60 |
| Novita AI | $0.05 / $0.25 | $0.30 / $1.20 | Second cheapest for gpt-oss-120b |
| SiliconFlow | $0.05 / $0.45 | $0.15 / $0.60 | Sells DeepSeek V4.1 Flash at DeepSeek's off-peak price all day |
| Together AI | $0.15 / $0.60 | $0.30 / $1.20 | Matches DeepSeek's own peak price |
| Fireworks AI | $0.15 / $0.60 | $0.30 / $1.20 | Lists a cheaper spot rate for DeepSeek V4.1 Flash: $0.21 / $0.84 |
| Groq | $0.15 / $0.60 | Not offered | The fastest: about 500 tokens a second on gpt-oss-120b |
| DeepSeek | Not offered | $0.30 / $1.20 | Half price off-peak |
The gap is wider still on OpenRouter, where 22 hosts sell gpt-oss-120b for anywhere from $0.03 to $0.35 per million input tokens, a 12-times spread for the same model.
The cheapest provider isn't always the right one for a live app. Groq charges about four times DeepInfra's price for gpt-oss-120b, but it answers at about 500 tokens a second, which matters when a customer is waiting.
Which LLM API is totally free?
Google's Gemini API is the most useful free LLM API: Gemini 3.8 Flash, 3.6 Flash, and the Flash-Lite models cost nothing within rate limits, though Google uses free-tier prompts to improve its products. These are the free LLM APIs worth knowing:
| Provider | What's free | Limits | Uses your prompts for training? |
|---|---|---|---|
| Google Gemini API | Gemini 3.8 Flash, 3.6 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite, and more | Shown in your Google AI Studio account | Yes |
| OpenRouter | 12 free models, including Gemma 4 and NVIDIA Nemotron | 20 requests a minute and 50 a day, or 1,000 a day once you've bought $10 of credits | Depends on the host |
| Z.ai | GLM-4.7-Flash and GLM-4.5-Flash | Not published | Not stated |
| Groq | A free plan with lower rate limits | Shown in your Groq console | No |
| Cloudflare Workers AI | 10,000 Neurons a day (about 11 cents of usage) | Then $0.011 per 1,000 Neurons | No |
| Cohere | A trial key | 1,000 calls a month, and not for production | Not stated |
Two free options that used to top these lists are gone. GitHub Models shut down on July 30, 2026, and Mistral's free plan no longer includes API access. Cerebras now gives a one-off $5 credit instead of a free tier.
Free tiers are great for testing and side projects. For anything with real customers, budget for a paid model: free limits are tight, and customers don't love having their messages used for training.
What is the cheapest LLM API for chatbots, coding, and agents?
The cheapest LLM API depends on the job: Claude Haiku 5.5 or GPT-6 Luna for chatbots, GPT-6.1 Terra or DeepSeek V4.1 Flash for coding agents, Qwen3.7-Flash or gpt-oss-20b for bulk jobs, and Gemini 3.1 Flash-Lite for long documents.
Cheapest LLM API for a chatbot
Claude Haiku 5.5 and GPT-6 Luna are the cheapest LLM APIs for a chatbot that sounds smart. Both cost $0.10 per million input tokens and $0.50 output, so with prompt caching a typical reply costs about $0.0003. That's $2.88 for 10,000 replies.
The shop chatbots I build use a small, cheap model to work out what the customer wants and a bigger model to write the reply. That keeps a message to about a cent, and the bot still sounds like it knows the shop inside out. If you'd rather not build one yourself, here are the best AI chatbots for small business.
Cheapest LLM API for coding and agents
GPT-6.1 Terra at medium effort gives the most for the money on agent-style tasks: 38 on Artificial Analysis for $0.17 a task. If you'd rather pay the lowest token price, DeepSeek V4.1 Flash costs $0.30 in and $1.20 out at peak, and its cached input is just $0.006 per million. That matters because coding agents resend your code on every step. xAI's Grok Build 0.1 ($1 in, $2 out) is the cheapest model built just for coding.
Cheapest LLM API for bulk jobs
Qwen3.7-Flash ($0.03 in, $0.13 out) and gpt-oss-20b on DeepInfra ($0.03 in, $0.14 out) are the cheapest for tagging, sorting, and pulling data out of text at volume. Use a batch API where you can: OpenAI, Anthropic, Google, Mistral, and Alibaba take 50% off jobs you don't need answered straight away.
Cheapest LLM API for long documents
Gemini 3.1 Flash-Lite is the cheapest LLM API for long documents: $0.25 in and $1.50 out, with a 1M-token context and no long-prompt surcharge. Watch the surcharges elsewhere. Claude Haiku 5.5 costs five times as much on prompts over 100K tokens, OpenAI charges more above 272K, xAI doubles the whole request at 200K, and Qwen3.7-Flash goes up after just 32K.
Which big AI lab has the cheapest LLM API?
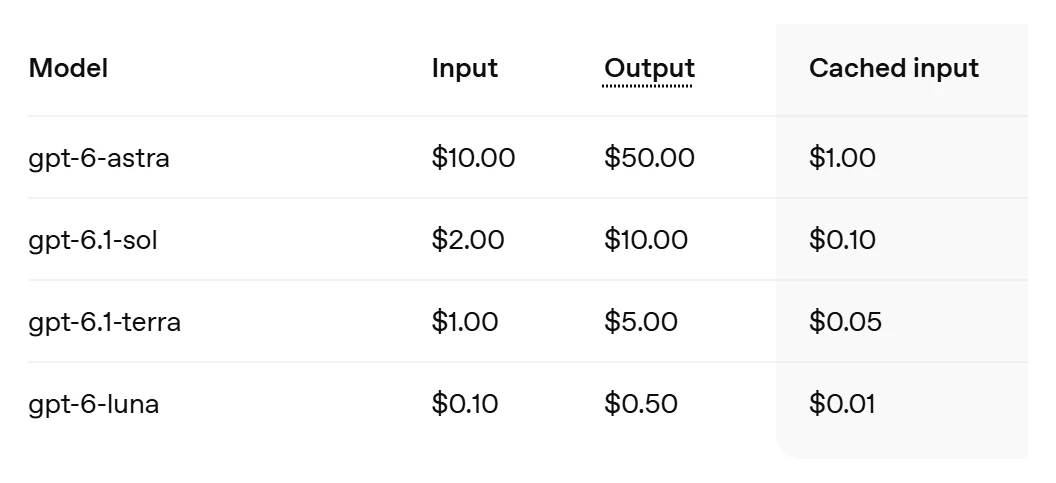
OpenAI and Anthropic tie for the cheapest model from a big US lab: GPT-6 Luna and Claude Haiku 5.5 both cost $0.10 per million input tokens and $0.50 output. Haiku scored higher on Artificial Analysis's tests (36 vs 28), but it costs five times as much once a prompt goes over 100K tokens.
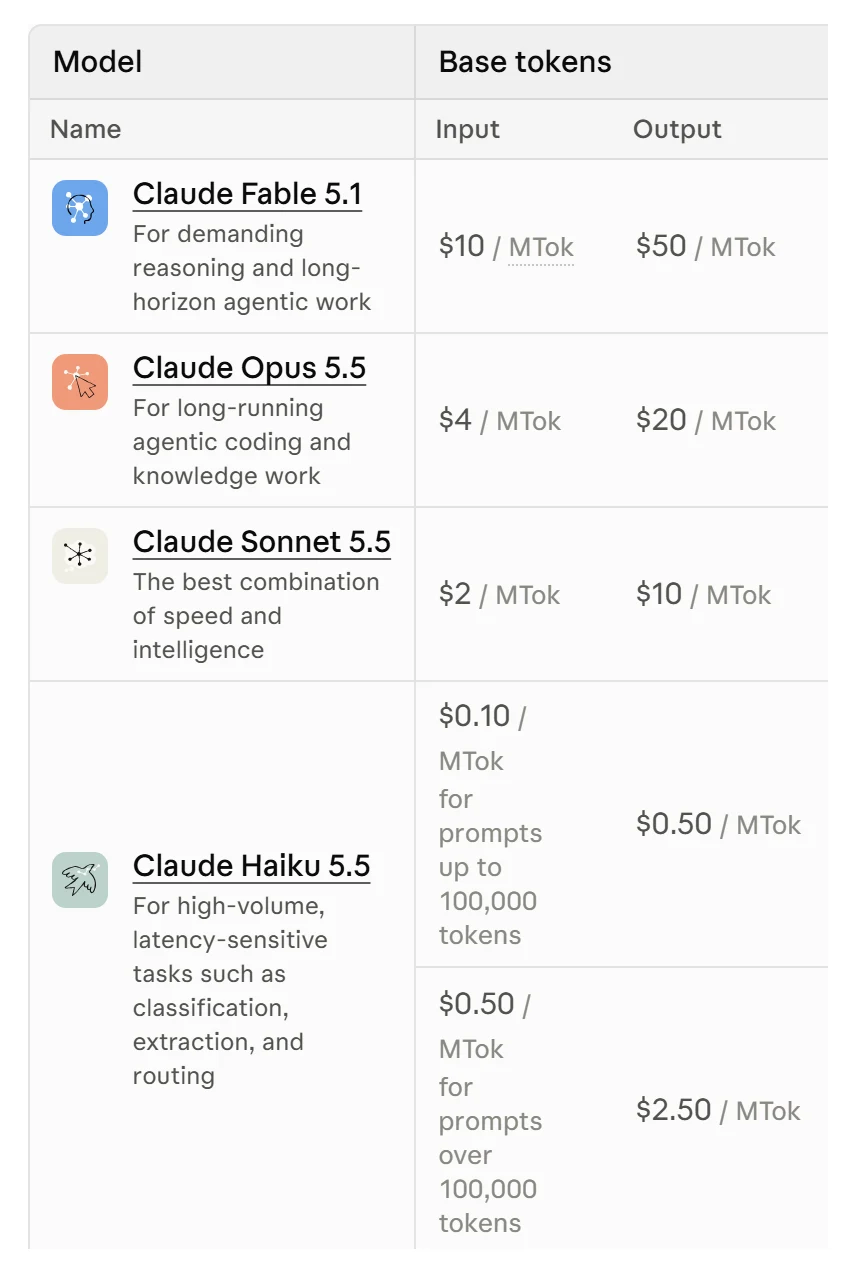
Google's cheapest current model, Gemini 3.1 Flash-Lite, costs $0.25 and $1.50. The older Gemini 2.5 Flash-Lite is cheaper at $0.10 and $0.40, but Google only offers it to people who've used it before. At the top end, the flagships cost 100 times more: GPT-6 Astra and Claude Fable 5.1 are both $10 in and $50 out.
Here are OpenAI's and Anthropic's own price tables:
Is DeepSeek the cheapest LLM API?
No. DeepSeek V4.1 Flash costs $0.30 per million input tokens and $1.20 output at peak times, which is more than GPT-6 Luna or Claude Haiku 5.5. Off-peak it's half that, and its cached input costs just $0.006 per million ($0.003 off-peak).
Peak is 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays. That's 8 to 11pm and 1 to 5am on the US East Coast, so a US working day is all off-peak. In Australia, peak lands at noon to 3pm and 5 to 9pm (AEDT). Here's DeepSeek's own price table:
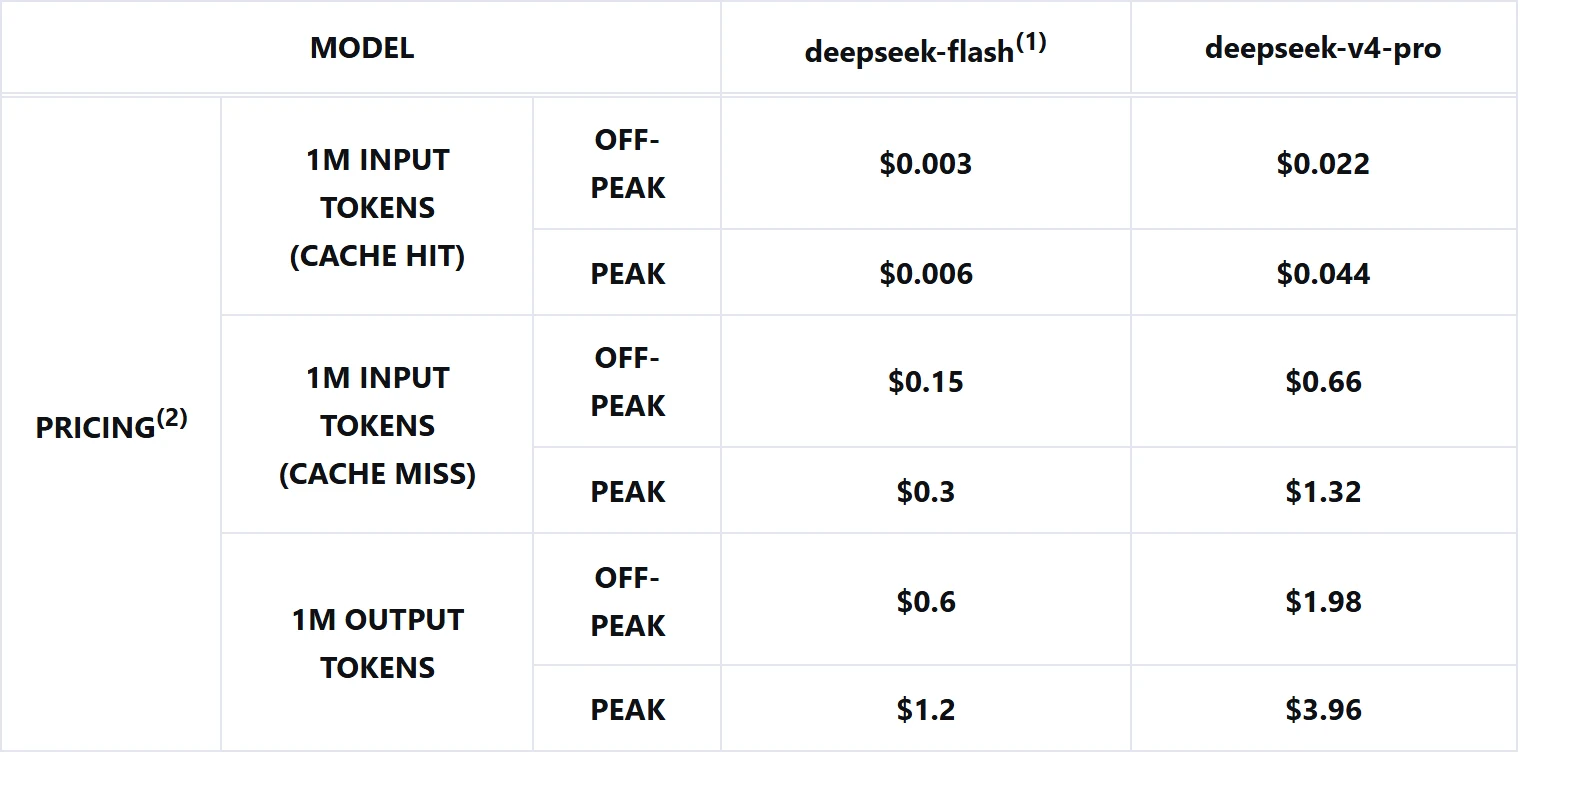
DeepSeek's models are open, so other hosts sell them too. DeepInfra charges $0.14 in and $0.42 out for DeepSeek V4.1 Flash at any hour (30% off its usual $0.20 and $0.60), and Together AI and Fireworks AI match DeepSeek's peak price. DeepSeek is a Chinese company, so if you'd rather your data stayed with a US host, those three run the same model.
How to make LLM API calls cheaper
The biggest savings come from prompt caching, the batch API, and sending easy jobs to a smaller model, and you can stack all three. Here's how to make LLMs cheaper, from the biggest saving down:
- Cache everything that repeats. Cached input costs 90% less on most models: GPT-6 Luna charges $0.01 instead of $0.10, and DeepSeek V4.1 Flash $0.006 instead of $0.30. Put the parts that never change (instructions, product info, the chat so far) at the start of the prompt, so every new message reuses them. OpenAI and Anthropic charge a little extra to write to the cache, so it pays off when a prompt gets reused.
- Don't cut the chat history to save money. It's tempting to only send the last few messages, but then your bot forgets what the customer said three messages ago. Cache the history instead: it costs a tenth as much and the bot remembers everything.
- Use the batch API for anything that can wait. OpenAI, Anthropic, Google, and Mistral take 50% off, xAI takes 20% off, and Kimi charges 60% of the normal price.
- Send easy jobs to a small model. Let a cheap model sort the simple questions and only call the big one when it's needed. That's how I keep chatbot replies to about a cent.
- Turn the thinking down. Reasoning tokens are billed as output. On Artificial Analysis's tests, GPT-6 Luna cost $0.07 a task at high effort and $0.15 at max, and Claude Haiku 5.5 cost $0.16 at high and $0.41 at max. For simple jobs, low or no thinking is plenty.
- Run DeepSeek off-peak. It's half price outside 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays.
- Keep prompts under the long-context line. Claude Haiku 5.5 costs five times as much over 100K tokens, OpenAI's prices rise over 272K, and xAI doubles at 200K.
- Shop around for open models. The same model can cost very different amounts depending on the host: gpt-oss-120b is $0.15 in and $0.60 out on Groq and Together, and $0.037 and $0.17 on DeepInfra.
How much do LLM APIs cost?
LLM APIs cost between about $0.02 and $50 per million tokens, and you pay separately for the text you send (input) and the text the model writes back (output). Output tokens usually cost about five times as much as input tokens.
A token is a chunk of a word, about three-quarters of a word on average in English. So a million tokens is roughly 750,000 words, or about 10 novels. If you're new to LLMs, my guide to natural language processing explains how they read and write text.
Here's a real example. A chatbot reply with 3,000 tokens of instructions and chat history (60% of it cached) and a 300-token answer costs $0.0003 on Claude Haiku 5.5 or GPT-6 Luna, $0.0056 on Claude Sonnet 5.5, and $0.011 on Claude Opus 5.5. At 10,000 replies a month, that's $2.88, $55.80, or $111.60.
To work out your own bill, put your token counts into the LLM cost calculator. It prices all 38 models per request and per month, with caching, batch, and off-peak discounts.
Is OpenRouter cheaper than going direct?
OpenRouter is rarely cheaper than going direct, because it passes on each provider's token price with no markup but adds a 5.5% fee when you buy credits.
Where it does save money is open models: one key reaches dozens of hosts, and some of them undercut everyone. The catch is that the cheapest hosts often run compressed (fp4) versions that can be a little dumber, so check which host you're actually getting.
Which LLM API prices are changing soon?
Google is doubling two of its prices: Gemini 4 Argon goes to $4 in and $20 out on December 1, 2026, and Gemini 3.8 Flash and 3.6 Flash go to $1.50 and $7.50 on January 1, 2027. Here's everything else that's changing:
- OpenAI shuts down gpt-5, gpt-5-mini, and gpt-5-nano on December 11, 2026, and older GPT-4 models, including GPT-4o and GPT-4o mini, on January 14, 2027.
- From December 1, 2026, calls to Gemini 2.5 Pro and 2.5 Flash go to Gemini 3.8 Flash and 3.5 Flash-Lite, at those models' prices.
- Moonshot stopped new sign-ups for its Kimi K2 models on October 31, 2026, and retires them by the end of December.
AI prices move fast, usually down. The AI newsletters I read are the quickest way to hear about a price cut.
Is it cheaper to run an LLM locally?
Running an LLM locally is free per token, so if you already own a computer with 16GB of memory or more, it beats every API on price.
The catch is quality and speed. The models that fit on a laptop, like Qwen3.5 9B or gpt-oss-20b, are well behind GPT-6.1 Terra or Claude Sonnet 5.5, and a big graphics card costs more than years of API calls for most people. For private data or working offline, though, it's hard to beat. Here's how to run an LLM locally on a Mac, Windows, or Linux in about five minutes.